Hugging Face has replaced the in-house router behind Inference Providers, its serverless inference API for open models, with OpenRouter’s. Since November 16, language-model requests sent with a Hugging Face token go through OpenRouter, which picks among more than 80 providers per call by live price, speed and reliability. Existing code and prices stay the same, but developers can no longer use their own provider API keys for chat models.
What changes for developers
The endpoint does not move. The OpenAI-compatible router at https://router.huggingface.co/v1 and the InferenceClient in huggingface_hub and @huggingface/inference keep working with the same token. Hugging Face says the router accepts OpenAI’s Chat Completions and Responses APIs and Anthropic’s Messages API for every chat model.
What changes is provider choice. The old router sent a request to one provider and returned its error if it failed. Now a failed call is retried on the next-best provider within the same request, and traffic moves away from providers that slow down. A conversation stays with the provider holding its prompt cache; a stable UUID in an X-HF-Session-Id header makes that explicit.
Image, video and audio generation still run directly through Inference Providers, where custom keys for image and video providers keep working.
How to pick fastest, cheapest or a named provider
The default balances price, speed and reliability. A suffix on the model ID overrides it, as the Hugging Face blog shows with GLM-5.3:
zai-org/GLM-5.3            # default: best mix of price, speed and reliability
zai-org/GLM-5.3:fastest    # highest throughput
zai-org/GLM-5.3:cheapest   # lowest price
zai-org/GLM-5.3:novita     # only Novita
Hub model pages now have a Providers tab with each provider’s price, speed and 24-hour uptime, and users and organizations can switch off any provider in settings. OpenRouter says 160 models from 38 labs are available this way.
Billing and the end of custom keys
Hugging Face says prices are unchanged: you pay the provider’s rate on your Hugging Face bill with no markup. PRO users get $2 of monthly credits, and Team and Enterprise organizations get $2 per seat. Because chat traffic is now billed through Hugging Face, anyone who used their own provider keys must move that spending to their Hugging Face account.
One detail appears only in OpenRouter’s post. In OpenRouter’s October live test of its rebuilt routing, capacity errors fell 46 percent, time to first token improved 16.9 percent and throughput rose 16.3 percent, but cost per request went up 6.0 percent. These are OpenRouter’s own, unverified measurements.
How it compares with other AI gateways
| Option | Markup on tokens | Your own provider keys |
|---|---|---|
| Hugging Face Inference Providers | None, per Hugging Face | No longer for language models |
| OpenRouter directly | None on inference; 5.5% fee when buying credits | Yes; 5% fee above a monthly allowance |
| Vercel AI Gateway | None, per Vercel | Yes, on the paid tier |
The Hugging Face route suits teams already using Hub tokens, organization billing and plan credits. Teams with their own negotiated provider contracts lose out, since Hugging Face no longer accepts those keys for language models.
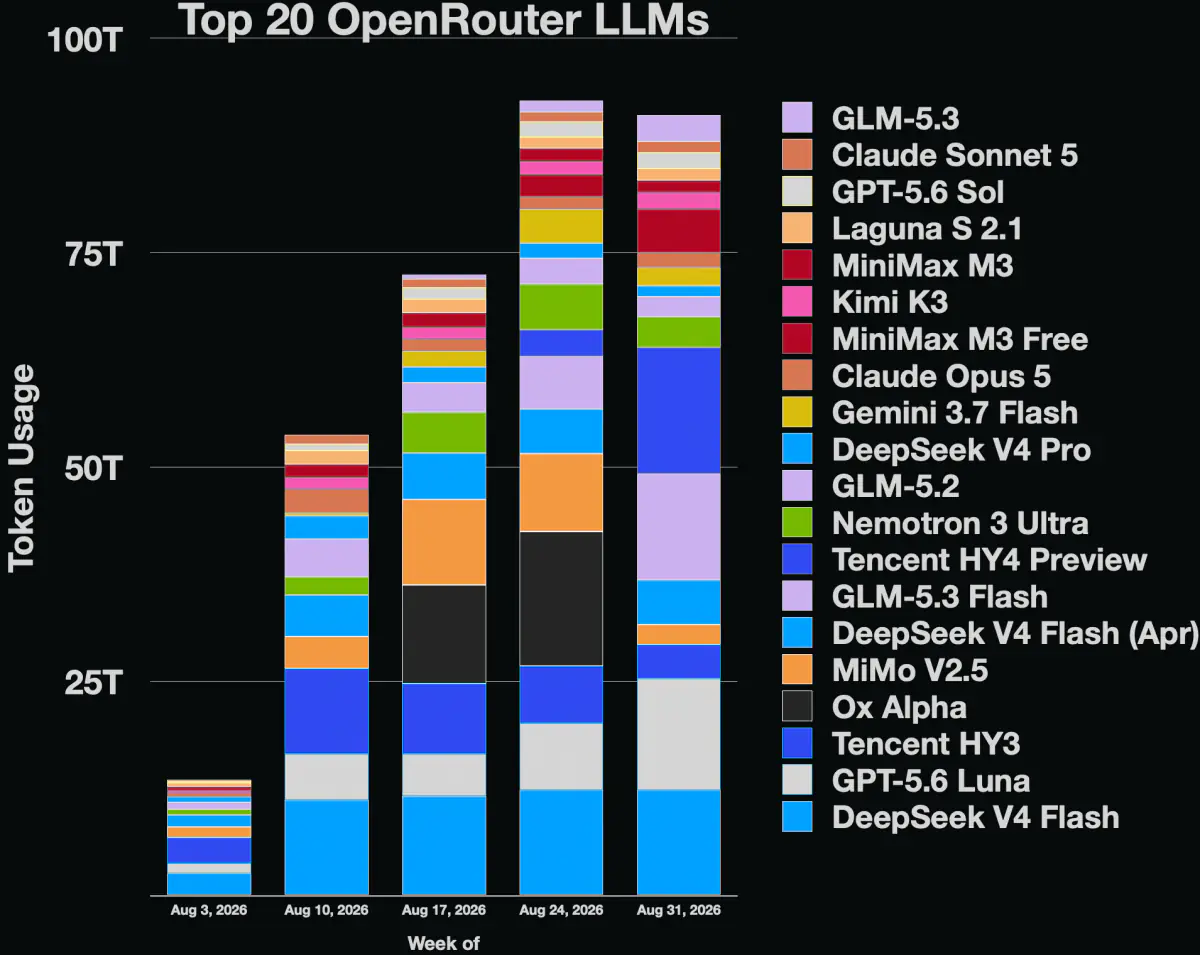
The bet behind the deal is open-weight models. Hugging Face cites OpenRouter data showing their share of OpenRouter tokens rising from 26.8 percent in October 2025 to 71.7 percent at the end of September 2026. Ownership is also shifting. According to The Decoder, Stripe agreed in August to acquire OpenRouter, and Nvidia’s reported purchase of Hugging Face is under review by the US Justice Department.
What to watch next
- When users can connect an OpenRouter account to Hugging Face, a planned next step.
- Which other tasks, such as embeddings or media, Hugging Face moves onto OpenRouter.
- Whether the 6 percent higher cost per request from OpenRouter’s test shows up on real Hugging Face bills.
- Whether the Nvidia and Stripe acquisitions change the partnership.
Key takeaways
- Language-model requests on Hugging Face Inference Providers now go through OpenRouter’s router.
- Endpoints, SDKs, tokens and prices stay the same; failed calls retry on another provider.
:fastest,:cheapestand provider-name suffixes on the model ID control routing.- Custom provider API keys no longer work for language models; image and video keys still do.
- OpenRouter’s own test found faster, more reliable routing at about 6 percent higher cost per request.
Frequently asked questions
Do I need to change my code to use the new routing?
No. The router URL, the InferenceClient libraries and your token keep working.
Can I still use my own provider API key on Hugging Face?
Not for language models, which are now billed to your Hugging Face account. You can still pick a provider with a suffix such as :novita.
Does Hugging Face add a fee on top of provider prices?
Hugging Face says it charges the provider’s price with no markup. Paid plans include monthly credits that are applied first.